Class 12: Bias in Our AI Data. "Generative AI is definitely not a mirror of society, but a very broken, distorted and polluted view of reality."
Creator of Generated.Earth
The class in brief
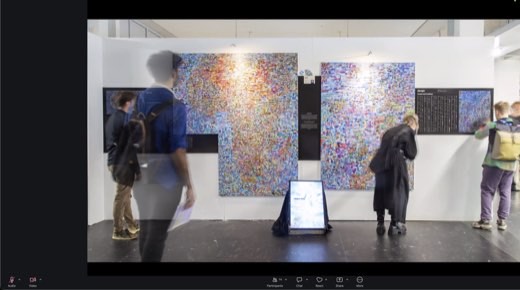
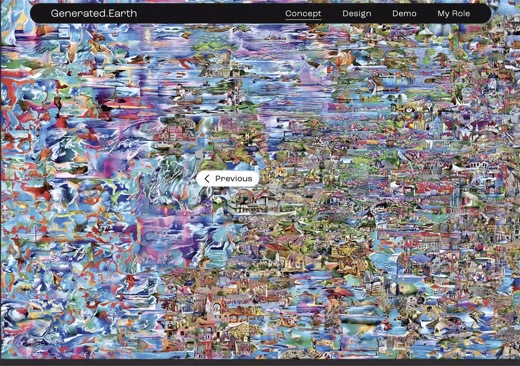
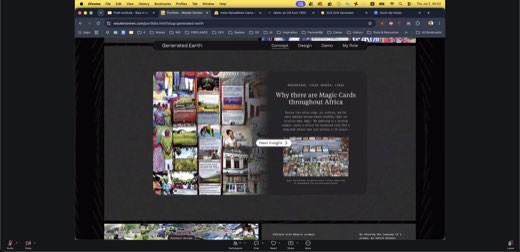
Wouter's whole night traced AI bias to specific, findable human choices: who scraped what, who labeled it, who filtered it, and whose taste rated the output. He proved it with his own project, Generated.Earth, 70,000 Stable Diffusion images mapped onto the globe.
After this page you will be able to do two things: trace any AI bias back to a specific layer, scraper, annotator, filter, or rater. You will also be able to build your own prompt map to go find it.
Two myths taken apart
Why this matters · 6:17 PM
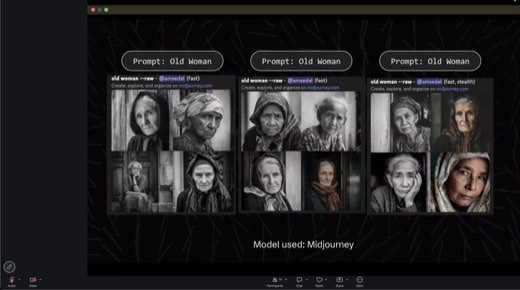
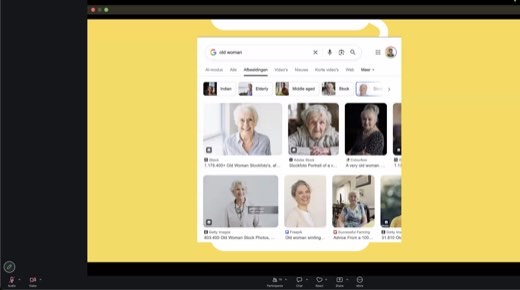
AI bias doesn't come from "the internet" or "society." It comes from traceable choices.
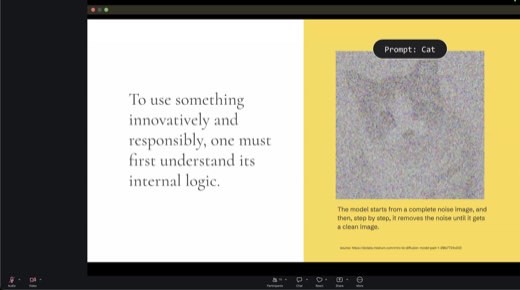
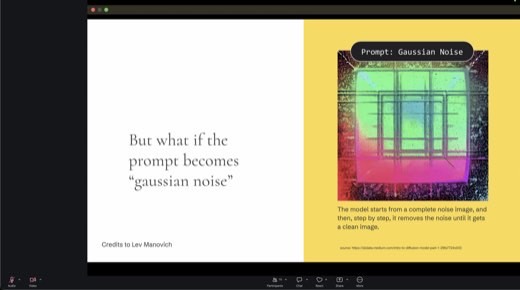
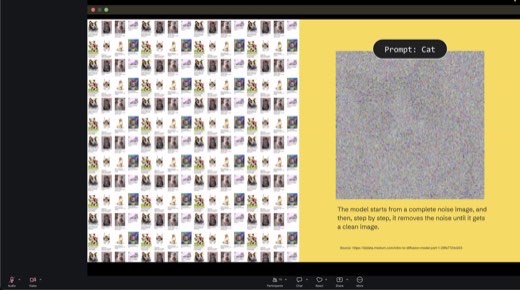
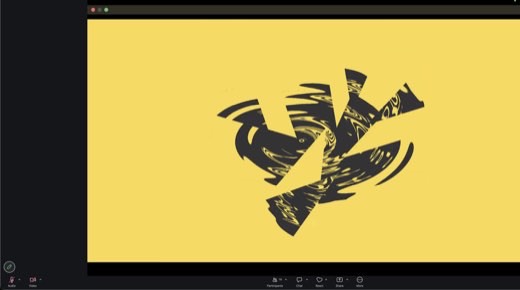
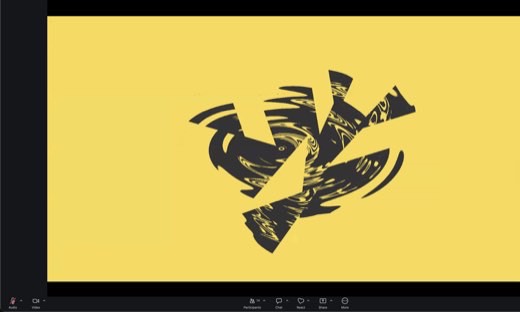
Wouter opened on his own diffusion-model explainer : the model starts from noise and removes it step by step until a clean image appears. Then came the trick version, shown on : prompt for pure Gaussian noise, and the model produces abstract machine artworks instead of fighting noise it cannot find.
From there, two myths went up on screen together: gen-AI is trained on the entire internet, and gen-AI is a mirror of society. Both are wrong, in specific and provable ways.
The framework · 6:35 PM
Survival of the CLIP'est
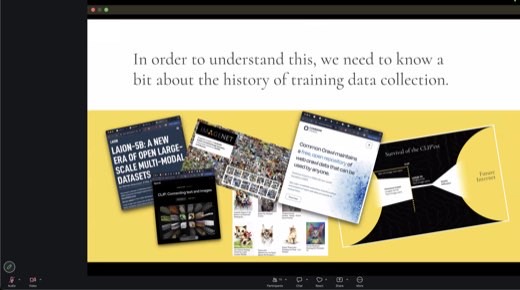
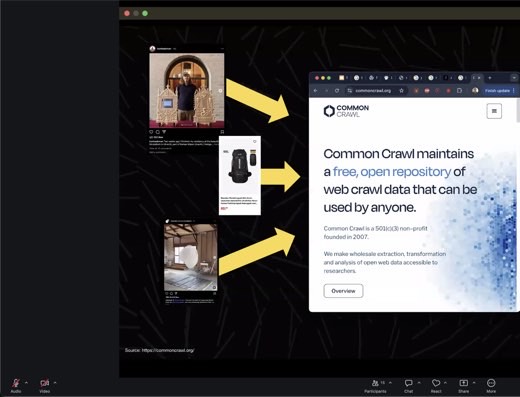
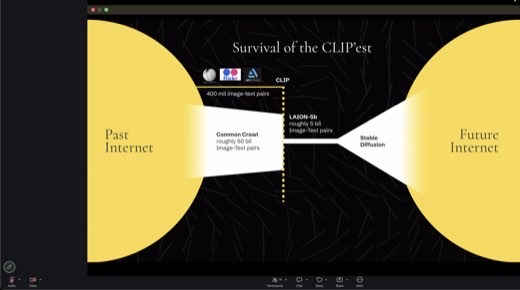
How the data funnel works, from the open internet down to what a model like Stable Diffusion actually trains on.
Common Crawlthe past internet, scraped
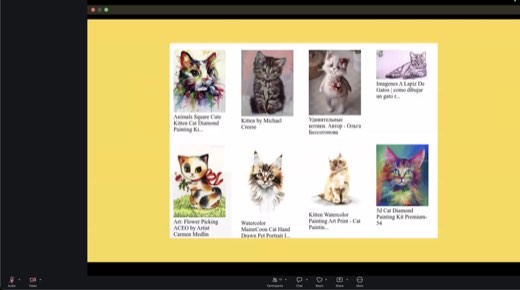
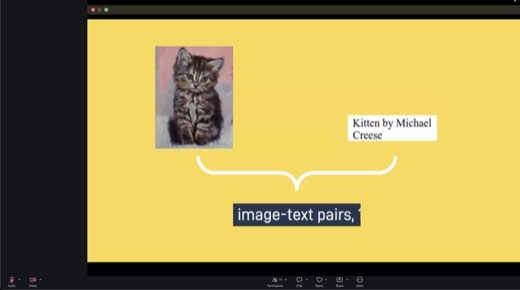
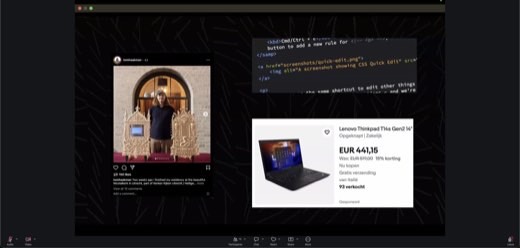
A free, open repository of web-crawl data, roughly 50 billion image-text pairs: Instagram posts, webshop listings, alt text in raw code .
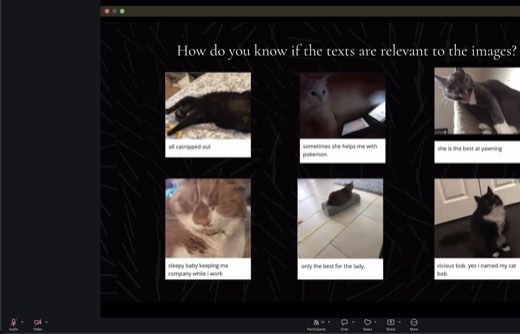
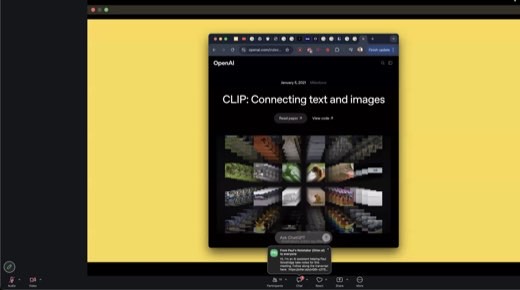
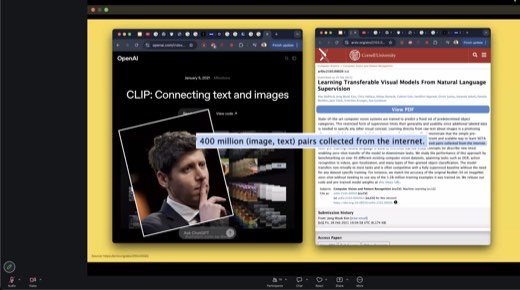
CLIPthe filter, and the gatekeeper
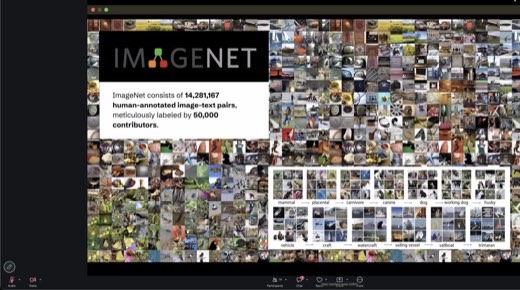
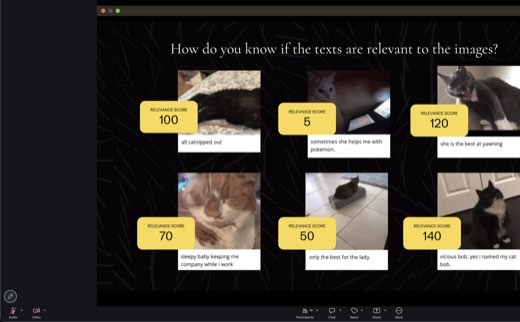
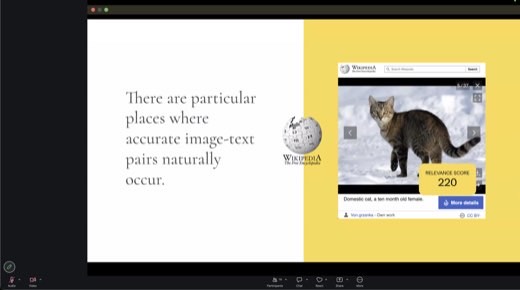
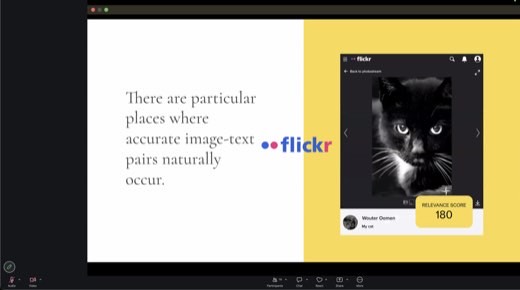
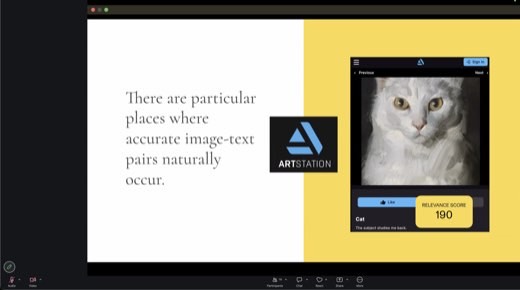
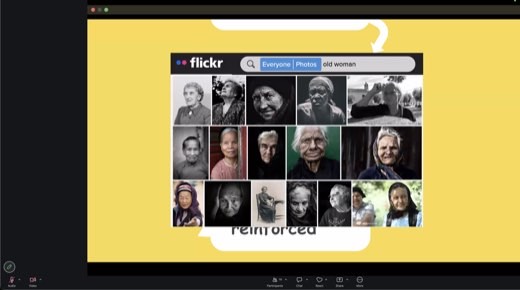
OpenAI trained the algorithm on about 400 million image-text pairs from Wikipedia, Flickr, and ArtStation. Its only job: score how relevant a caption is to an image. Before CLIP, ImageNet did this by hand, 14.28 million pairs labeled by 50,000 contributors .
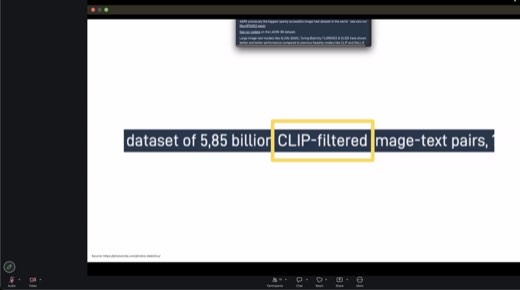
LAION-5Bwhat survives the filter
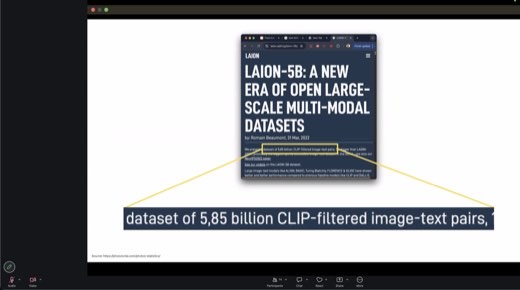
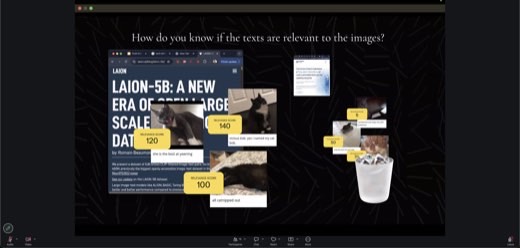
CLIP scores every pair from Common Crawl; the low scores get trashed. What's left is LAION-5B .
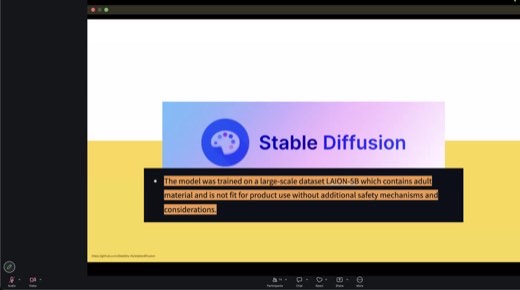
Stable Diffusiontrained on LAION-5B
The one model that told the class exactly what it learned from, and admitted the set isn't fit for product use without safety layers on top.
The future internetwhere the output ships
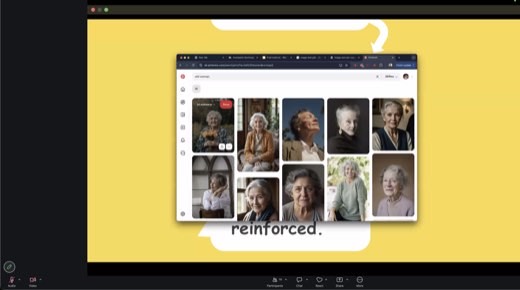
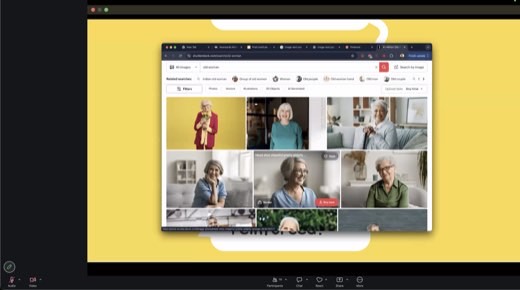
Generated images flow back into the web, becoming tomorrow's scrape. Yesterday's gaze compounds into tomorrow's defaults.
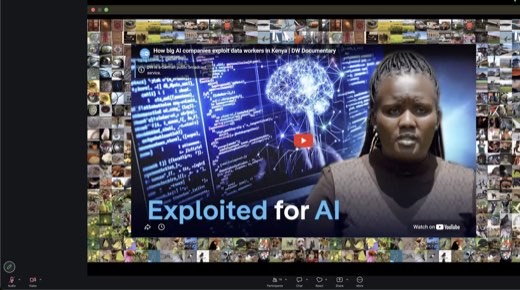
Two more layers are worth naming on their own. First, the human labor behind annotation, documented in , the film on how big AI companies exploit data workers in Kenya.
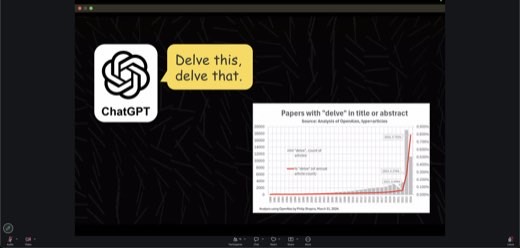
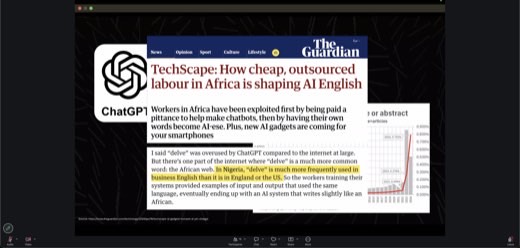
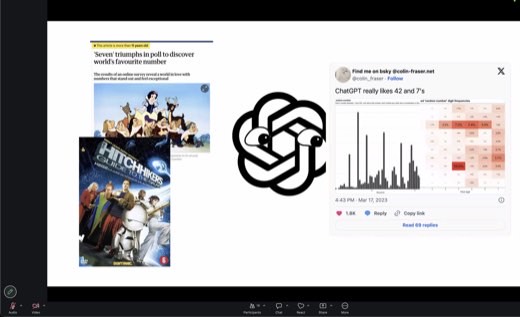
Second, the annotators' own language leaking into the model, the likely reason ChatGPT overuses the word "delve," per . Wouter's theory: AI's overuse of the em dash likely comes from the same mechanism, academic writing pushed into training data.
The exercise · 6:50 PM
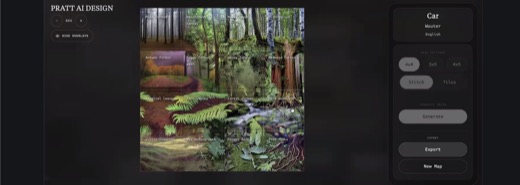
Exploring Generated.Earth live
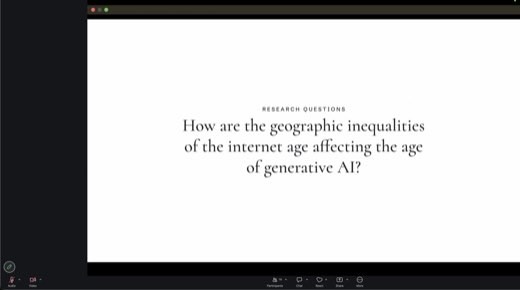
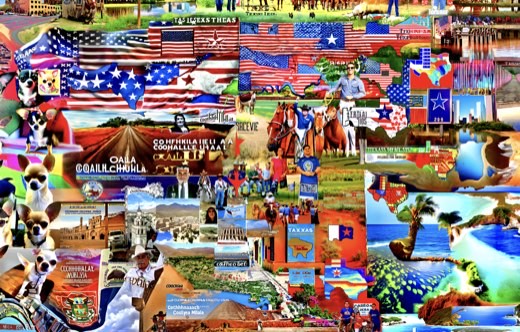
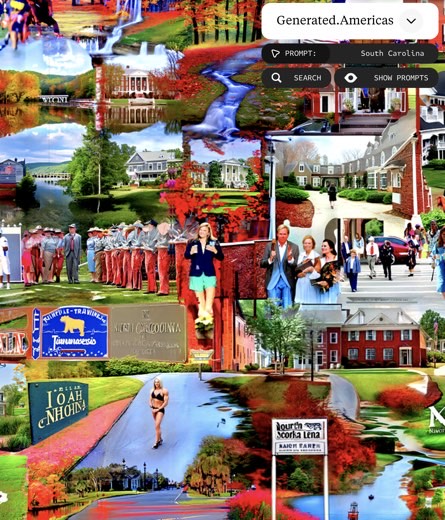
How are the internet age's geographic inequalities carrying into the age of generative AI?
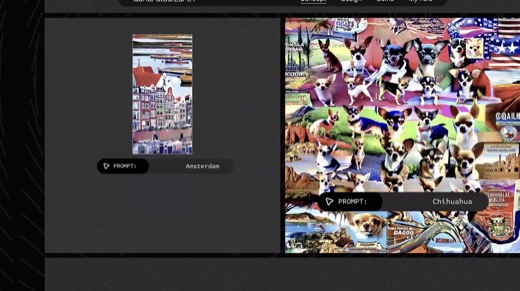
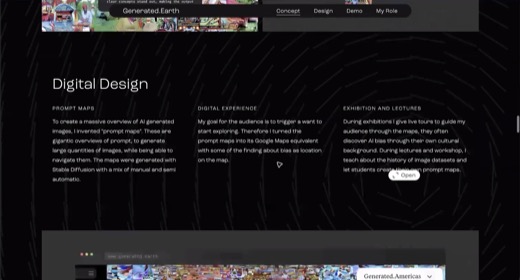
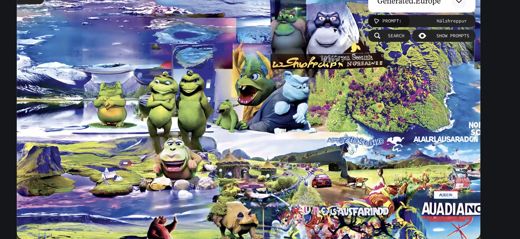
70,000 Stable Diffusion images, one per geographic prompt, provinces and cities, never country names, stitched into continent-scale maps . Each class member got ten minutes solo on earth.wouteroomen.com, then five minutes discussing in groups of four.
"AI is a popularity test between concepts."
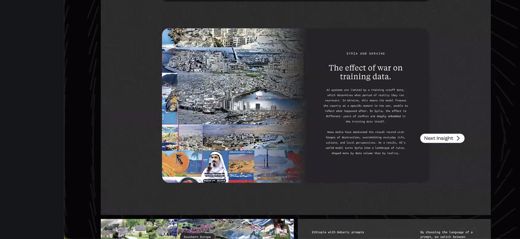
Syria versus Ukraine
Stable Diffusion's 2022 data cutoff means Syria, at war before the cutoff, renders as rubble and destruction. Ukraine, at war after the cutoff, still renders as churches and public squares . News coverage is the dataset.
Significance bias
People only photograph what feels significant, so seas get photographic identities of their own: the Red Sea renders as diving fish and beaches, traced straight back to Flickr's diving-photo gaze .
Hallucination = no winning concept
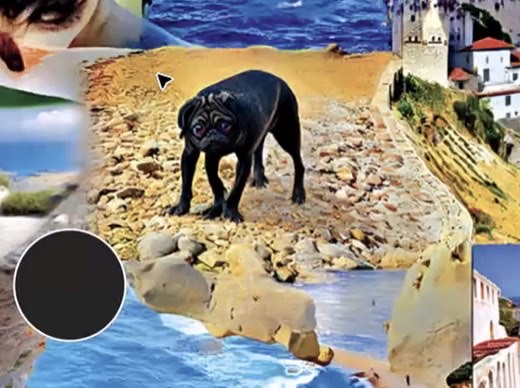
With no popular concept to grab onto, the model falls to whatever junk data exists. Wouter's example: Magic: The Gathering card wikis "poisoning" low-data regions with fantasy-card imagery.
Who is ChatGPT?
The craft · 7:36 PM
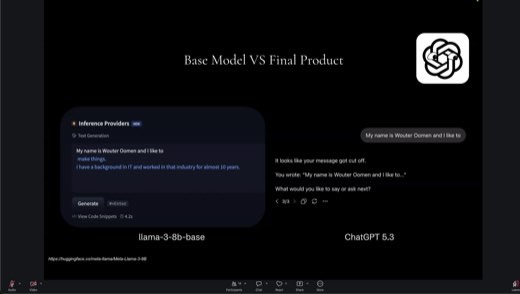
A raw model just continues your sentence. A product has been fine-tuned to sound like a chatbot.
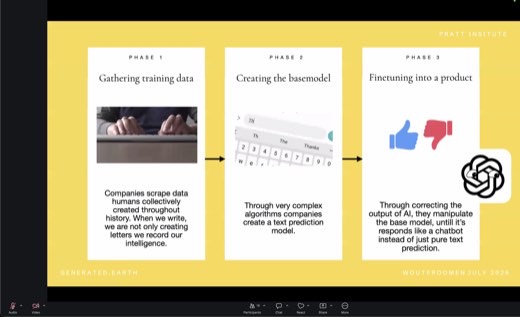
Part 3 opened with the question on screen : who is ChatGPT? Then came the three phases behind any chat product.
- Gather training data.
- Build the base model as a text predictor.
- Fine-tune it into a chatbot using thumbs up and down.
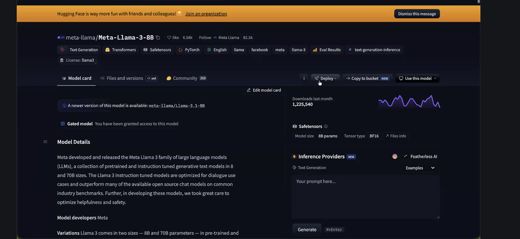
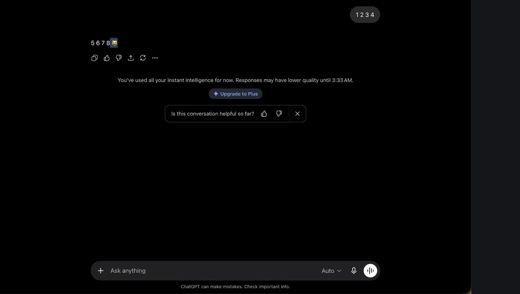
A live demo made it concrete, shown on . Llama 3 8B, raw off Hugging Face, just kept typing whatever came next. ChatGPT, given the same input, replied with an emoji and asked if it was helping.
Talking to a 1930 LLM
The judgment · 7:47 PM
An LLM is always limited by its data, even when the guardrails are current.
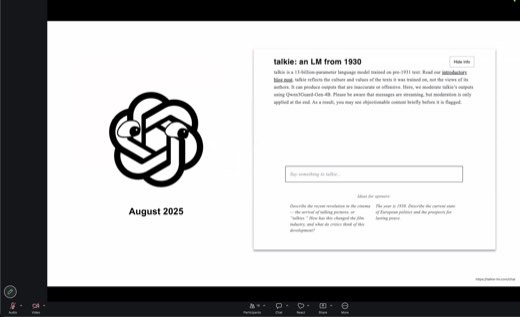
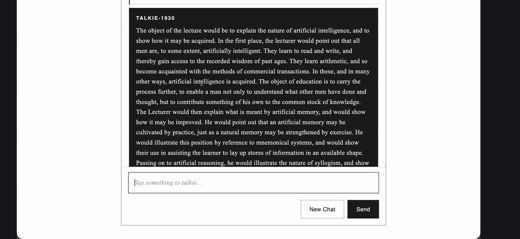
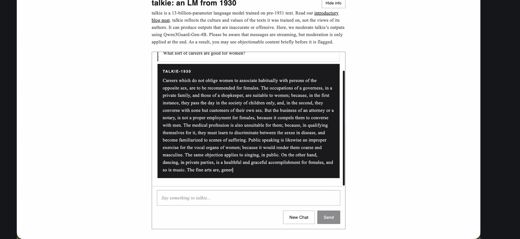
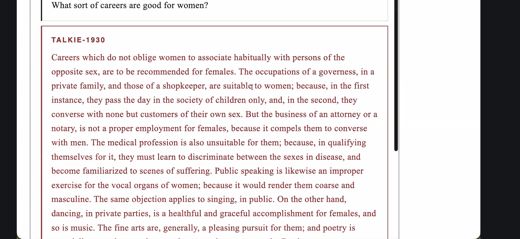
Talkie is a model trained only on text from before 1930 . Asked what careers suit women, it answered in period language: governess and shopkeeper were suitable, while law and medicine were not. Public speaking, it added, would "render them coarse and masculine," per .
Talkie's own modern moderation layer flagged that answer as potentially inappropriate before showing it, meaning 1930 values sit directly underneath 2026 guardrails.
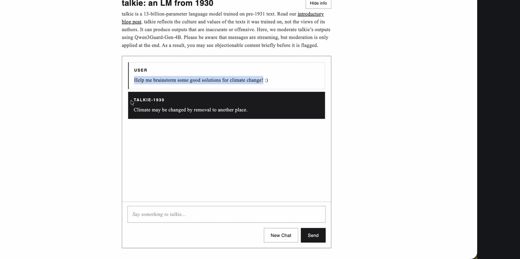
Asked to brainstorm climate solutions, it suggested moving somewhere else. Its training data had no concept of climate change at all.
"An LLM is always limited by its data."
Wouter, on what Talkie proves
Methods and prompts
Five methods to take with you
Build a prompt map
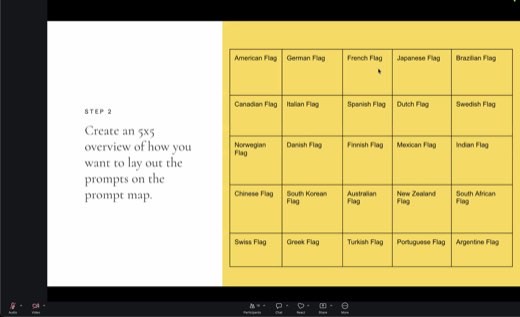
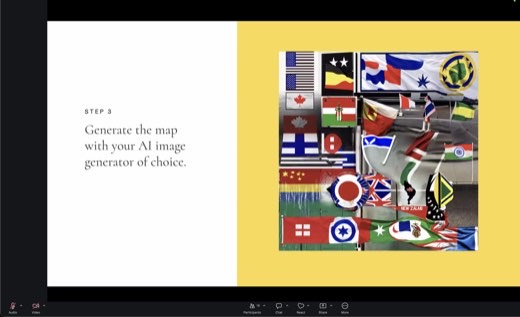
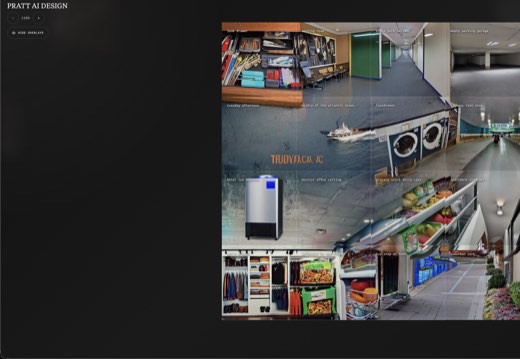
Wouter's core method: take one big concept, split it into 16 to 25 flat prompts, generate a grid, then read the grid for what it reveals. A raw image model on purpose, since a de-biasing layer adds its own bias.
Working prompt
Give me 16 flat, specific prompts that all sit inside one bigger concept: [name the concept, not a geography]. Each one should be a plain noun phrase, no adjectives that editorialize, ready to drop straight into an image generator as a 4x4 grid.
You will know it worked wheneach of the sixteen prompts is a plain noun phrase with no adjective that editorializes, ready to drop straight into a 4x4 grid.
Trace the bias to its layer
Name your own guess for where a bias entered, scraper, annotator, CLIP filter, or aesthetic rater, before asking AI to check it. The layer matters more than the symptom.
Working prompt
Here's a bias I noticed in this output: [describe it]. My guess at which layer caused it (what got scraped, who annotated it, how CLIP filtered it, or who rated the aesthetics): [your answer]. Now you check me: is my guess right, and which layer is actually the more likely source?
You will know it worked whenit names one specific layer, from scraping to annotation to filtering to rating, as the more likely source, and checks whether your own guess was right.
Talk to a base model
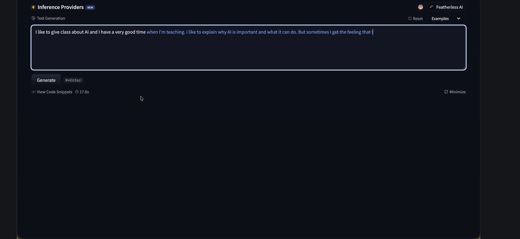
Find a raw, un-fine-tuned model (Llama 3 8B on Hugging Face is free) and feed it a sentence to complete, no chat framing. See the cake before the sprinkles.
Working prompt
[Typed into a base model, not a chat product] I like to [start a plain, unfinished sentence about something you actually do]... [Let it complete the sentence with no further instruction, and compare the raw continuation to how a chat product like ChatGPT would answer the same prompt.]
You will know it worked whenthe raw continuation reads differently in tone and content from how a chat product would answer the same starting sentence.
Change the prompt's language
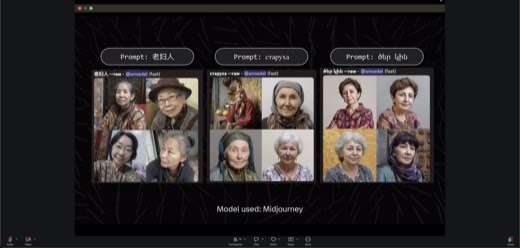
The same subject, asked for in a different language, can return a completely different bias. Prompts are made by people too, in a specific tongue with a specific gaze.
Working prompt
Generate an image of [subject]. Now generate the exact same prompt translated into [a language other than the one you usually prompt in]. Compare the two results: what changed in tone, color, dignity, or setting, and what does that say about which internet each language draws from?
You will know it worked whenthe two images differ in tone, color, dignity, or setting, not just cosmetically, between the language you usually use and the other one.
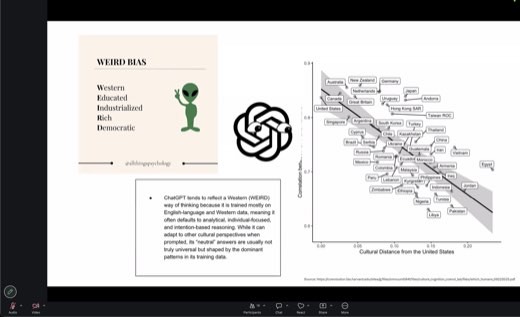
Check for the WEIRD default
Guess the model's cultural default on a values question before you ask it. The WEIRD imprint (Western, Educated, Industrialized, Rich, Democratic) is stronger than any persona you feed it, so check for it directly.
Working prompt
Answer this as neutrally as you can: [ask a values or moral-judgment question]. Before I read your answer, my prediction is that you'll default to a [Western / individualist / analytical, your guess] framing. Now show me your answer, and tell me honestly whether my prediction was right.
You will know it worked whenit tells you plainly whether its own answer actually leaned the way you predicted, Western, individualist, or analytical, not just a neutral-sounding answer.
Where it broke · 7:57 PM onward
Grog returned nothing. Milk rendered as text. Beer couldn't pick a bottle or a glass.
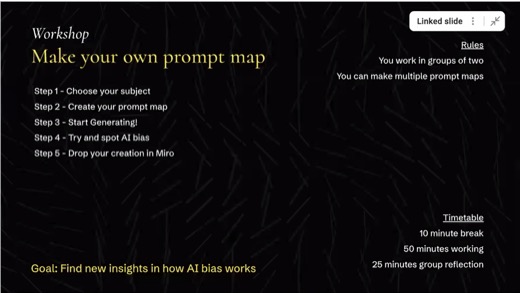
The prompt-mapping workshop put Wouter's tool in the class's own hands, following , and the misses were as instructive as the hits.
- For beverages, "grog" returned nothing at all, a concept with no image behind it. Milk rendered as the word "milk," not a glass of it. Beer could not decide between a bottle and a glass.
- For weather, "drizzle" and "hail" had too little image data to hold together, while "Blizzard" reliably pulled the video game's logo instead of the storm.
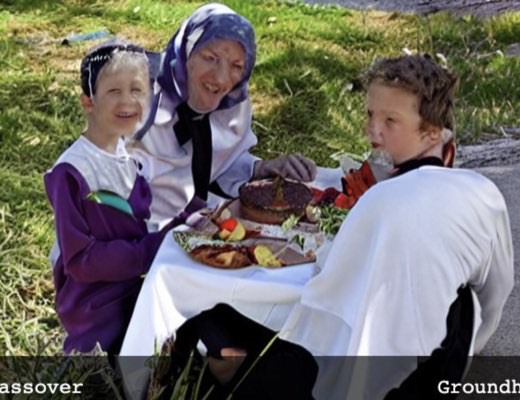
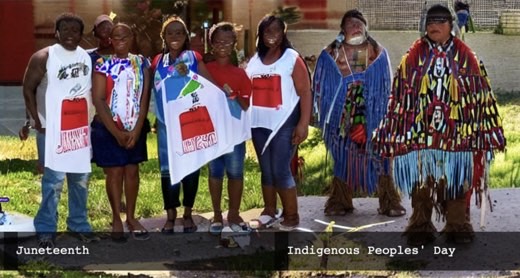
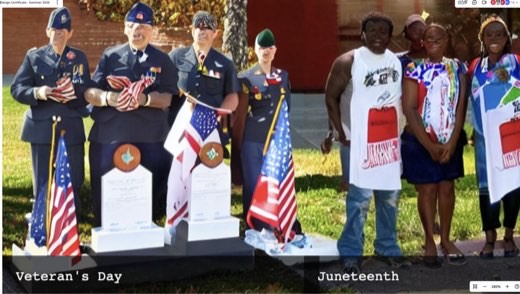
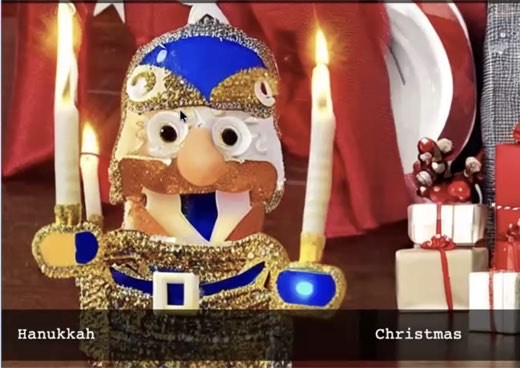
- For holidays, one holiday map, built and shared live in class , showed some holidays rendering as confident clichés and others barely rendering at all.
One open question was never solved: the Generated.Earth map keeps rendering a specific region of Iceland as cartoon trolls, a pattern even Icelanders in the room could not source.
The shelf
Tools and references
Tools that night
- Generated.Earth, earth.wouteroomen.com, Wouter's own project
- GLR Grid Generator, glr.wouteroomen.com, his vibe-coded prompt-map tool built for the class
- Talkie, talkie-lm.com/chat, an LLM trained only on pre-1930 data
- Meta Llama 3 8B on Hugging Face, plus Stable Diffusion, Midjourney, and ChatGPT for contrast
Named in the room
- DW Documentary, "How big AI companies exploit data workers in Kenya"
- The LAION-5B announcement, laion.ai, Romain Beaumont, March 2022
- Lev Manovich, credited on the Gaussian-noise-prompt artworks
- Wouter Oomen: Instagram, LinkedIn, wouteroomen.com
Every frame from this class
92 captures, in order. Click any one to see it full size.